v0.8.0 · 100% local · Apache-2.0
Find anything on your machine.
Semantic search for code, PDFs, notes, and docs.
Fully offline. No cloud. No telemetry. No subscription.
Ask in plain English — or any of 100+ languages — get back the
right file and line range in about a second, even when
the working directory isn't the right project.
$skygrep "where does the auth token get refreshed?"
═══ auth/middleware.py:78-94score 0.91 · python
async def renew_session(req: Request):
    # swap the access cookie when the refresh JWT is still valid
    if req.cookies.get("rt") and access_expired(req):
        return await refresh_token(claims, key)
$skygrep "the design doc on rate limiter rewrite"
═══ docs/rate-limiter-redesign.md:1-12score 0.87 · markdown
# Rate limiter redesign — Q3
We replace the leaky-bucket implementation with a sliding-window
log-based approach. [[wiki-link to design-2024-Q3]]
═══ designs/rate-limiter-2024Q3.pdf:p4  score 0.83 · pdf
Throughput projections under sustained 5k QPS load...
$skygrep "我昨天写的 cascade 调度代码"
═══ src/storage.py:847-892score 0.89 · python
def cascade_search(conn, query_embedding, *, ...):
    # σ-adaptive early-exit threshold (MacKay/Williams)
    tau_eff = max(CASCADE_TAU_FLOOR,
                  CASCADE_K_SIGMA * sigma_topK)
$cd /tmp/scratch && skygrep "where does the parallel umbrella dispatch?"
═══ ~/code/skylakegrep/src/cli.py:912-928score 0.86 · python · home-dir lazy hit
with ThreadPoolExecutor(max_workers=4) as ex:
    # cascade ‖ filename_extend ‖ lazy_cwd ‖ lazy_cross_folder
    cascade_fut   = ex.submit(_run_cascade, query, db_path)
    proactive_fut = ex.submit(_run_proactive, query, db_path)
    return _stream_first_confident(cascade_fut, proactive_fut)
17.982× median context reduction vs. an unbounded rg dump
·
53 / 60 quality-eligible public tasks
·
92.5 % retrieval-context quality
·
~1.1 s wrong-path first answer
·
100 % local
·
58 releases shipped
Three ways people use it
Show, don't tell.
Three real-shaped queries that demonstrate the value across
content types — code, docs, multilingual.
CODE BY CONCEPT
Find code by what it does, not what it's called.
You ask in plain English. The semantic substrate
(bge-m3) bridges your phrasing to the actual
identifier — even when the function name uses different
words from the query.
$skygrep "where does session refresh logic live?"
→ auth/middleware.py:78 · renew_session()
No rg hit for "session refresh"; semantic retrieval bridges to renew_session() from the project index.
CROSS-CONTENT
One query across code, PDFs, notes, and docs.
Markdown, PDF, Word, plain text — all indexed via the same
content-agnostic substrate. Your query searches all of
them at once, ranked by semantic relevance.
$skygrep "the design doc on rate limiter rewrite"
→ docs/rate-limiter.md · designs/q3-rewrite.pdf
Markdown link graph + PDF text-layer extraction in one cascade.
MULTILINGUAL · PRIVATE
Any language. Files never leave your laptop.
bge-m3 understands 100+ languages out of the
box. Index, retrieval, ranking, optional answer synthesis —
all run locally via Ollama. Zero network calls.
$skygrep "我昨天写的 cascade 调度代码"
→ src/storage.py:847 · cascade_search()
Mixed Chinese / English query. Zero network. Audit-friendly.
Command examples
Ask for the depth you need.
The bare command is intentionally fast for location and concept lookup.
Add depth only when you need file contents, synthesis, or structured
context for another agent. These examples are command patterns: run them
from the relevant project root, or add --include /
--lexical-root when an agent already knows the scope.
LOCATION
Find the right file first.
Use the bare form for where is..., find..., and
which file... questions. The router can answer from filename,
metadata, lexical, or semantic evidence without making you pick a lane.
$skygrep "where is the project brief I edited recently?"
→ docs/project-brief.md · scoped metadata / filename evidence
Fast path: return the path, skip unnecessary content reading.
CONTENT
Show the source text that supports the answer.
Add --content when the next step depends on what the
file says, not only where the file is.
$skygrep --content --detail standard "what does the API migration plan say about rollback?"
→ docs/migration-plan.md:42-58 · relevant snippet
Good default for human review and agent context.
DEEP READ
Read more after narrowing the target.
Use --detail full only when you intentionally want a
deeper local read. Bare --detail "query" is accepted as
shorthand for --detail full "query". Pair it with
--include to avoid dumping unrelated context.
$skygrep --content --detail full --include "docs/migration-plan.md" "show the deployment steps"
→ extended extracted text from the selected file
Higher depth, still scoped and local.
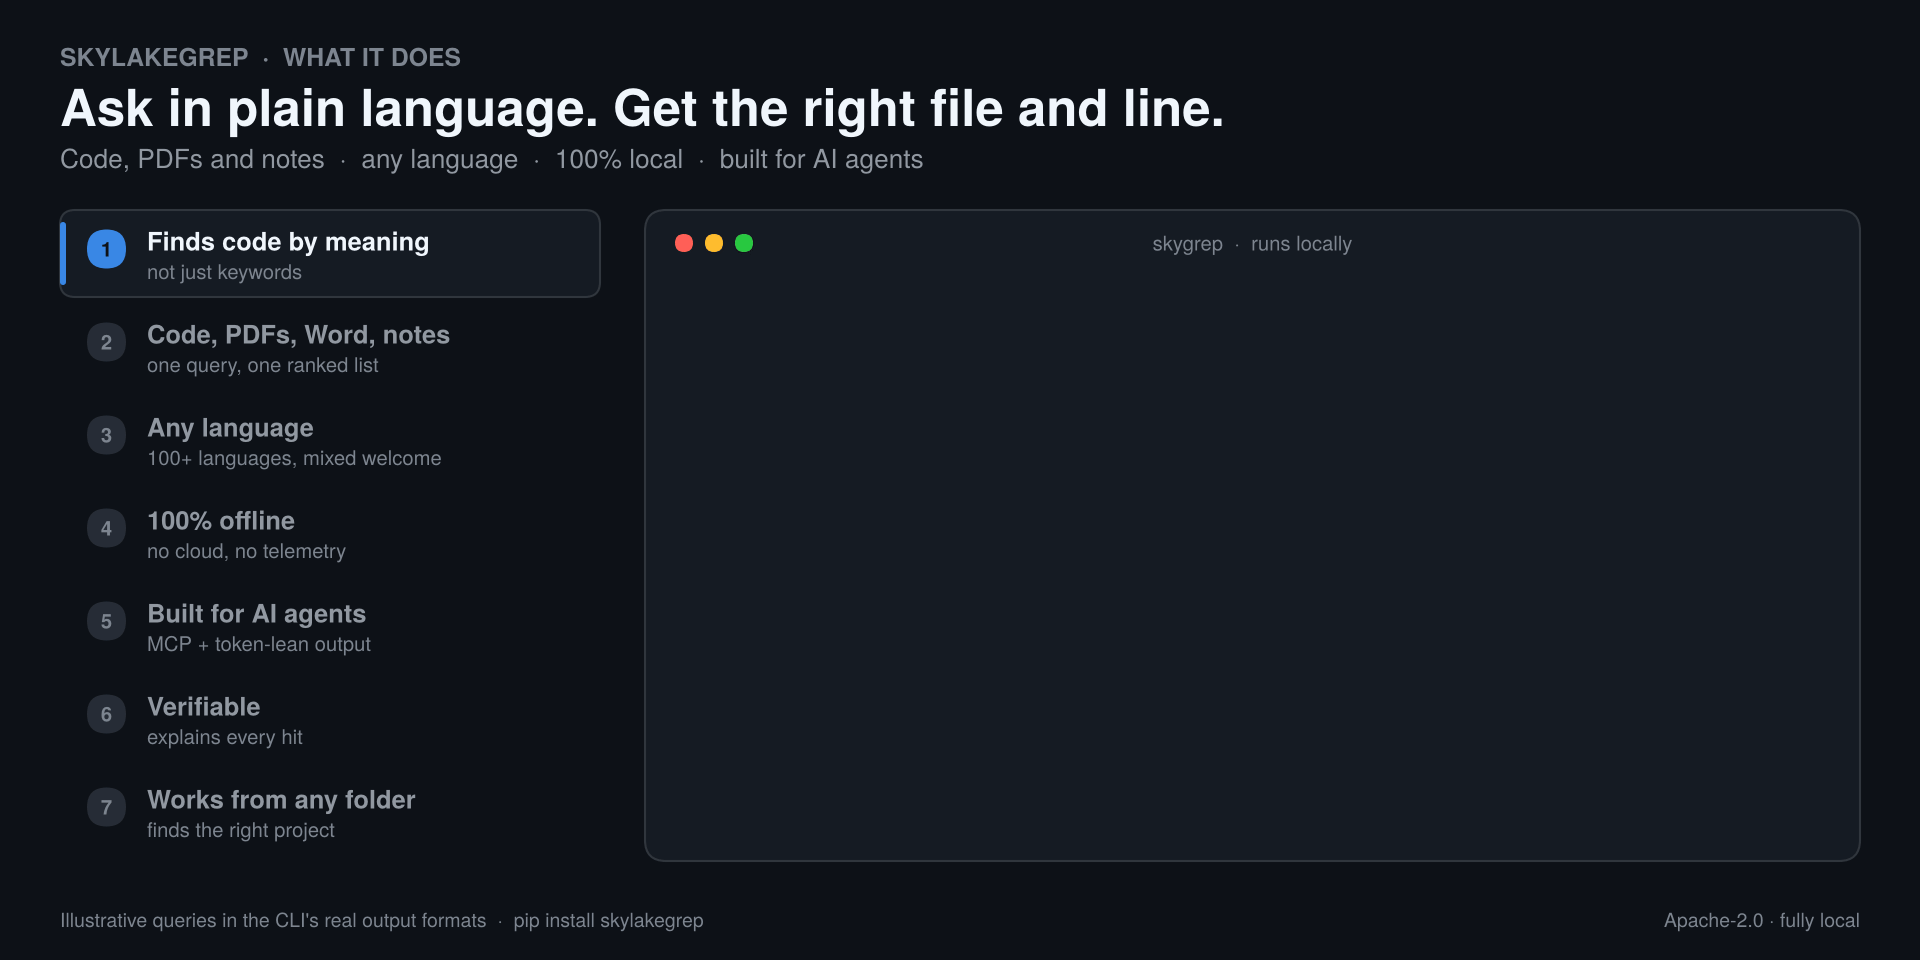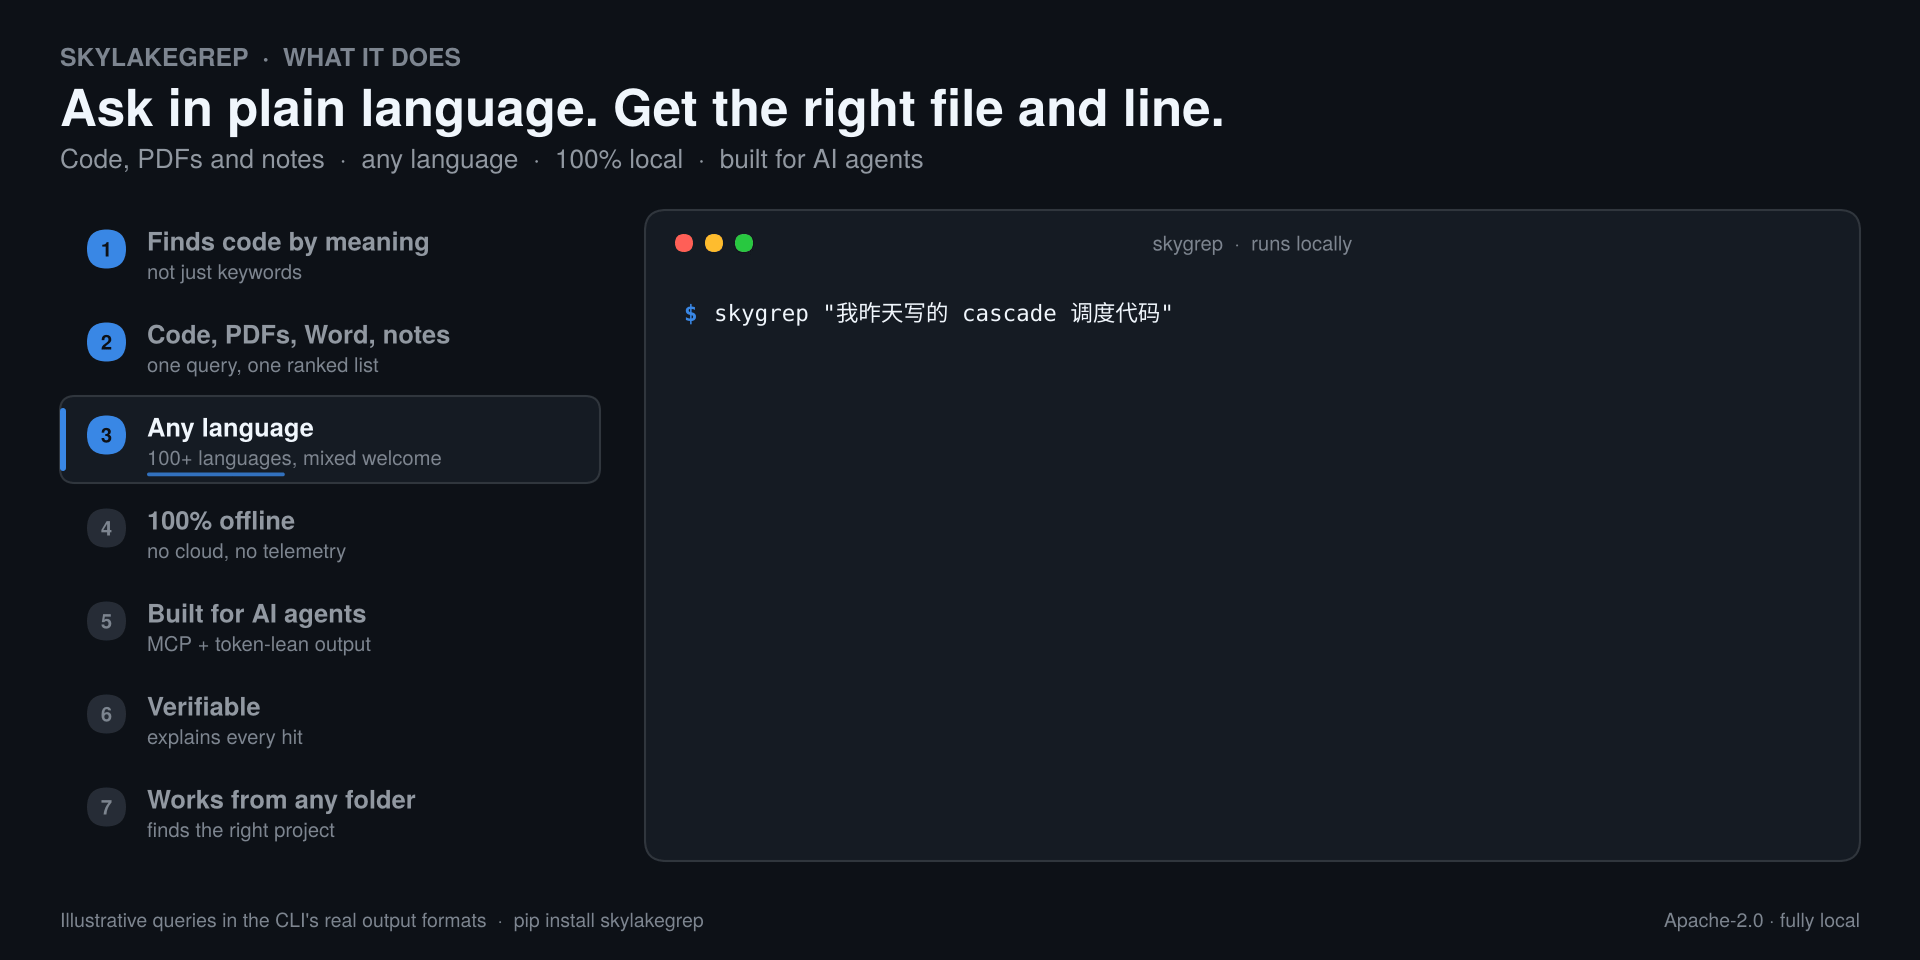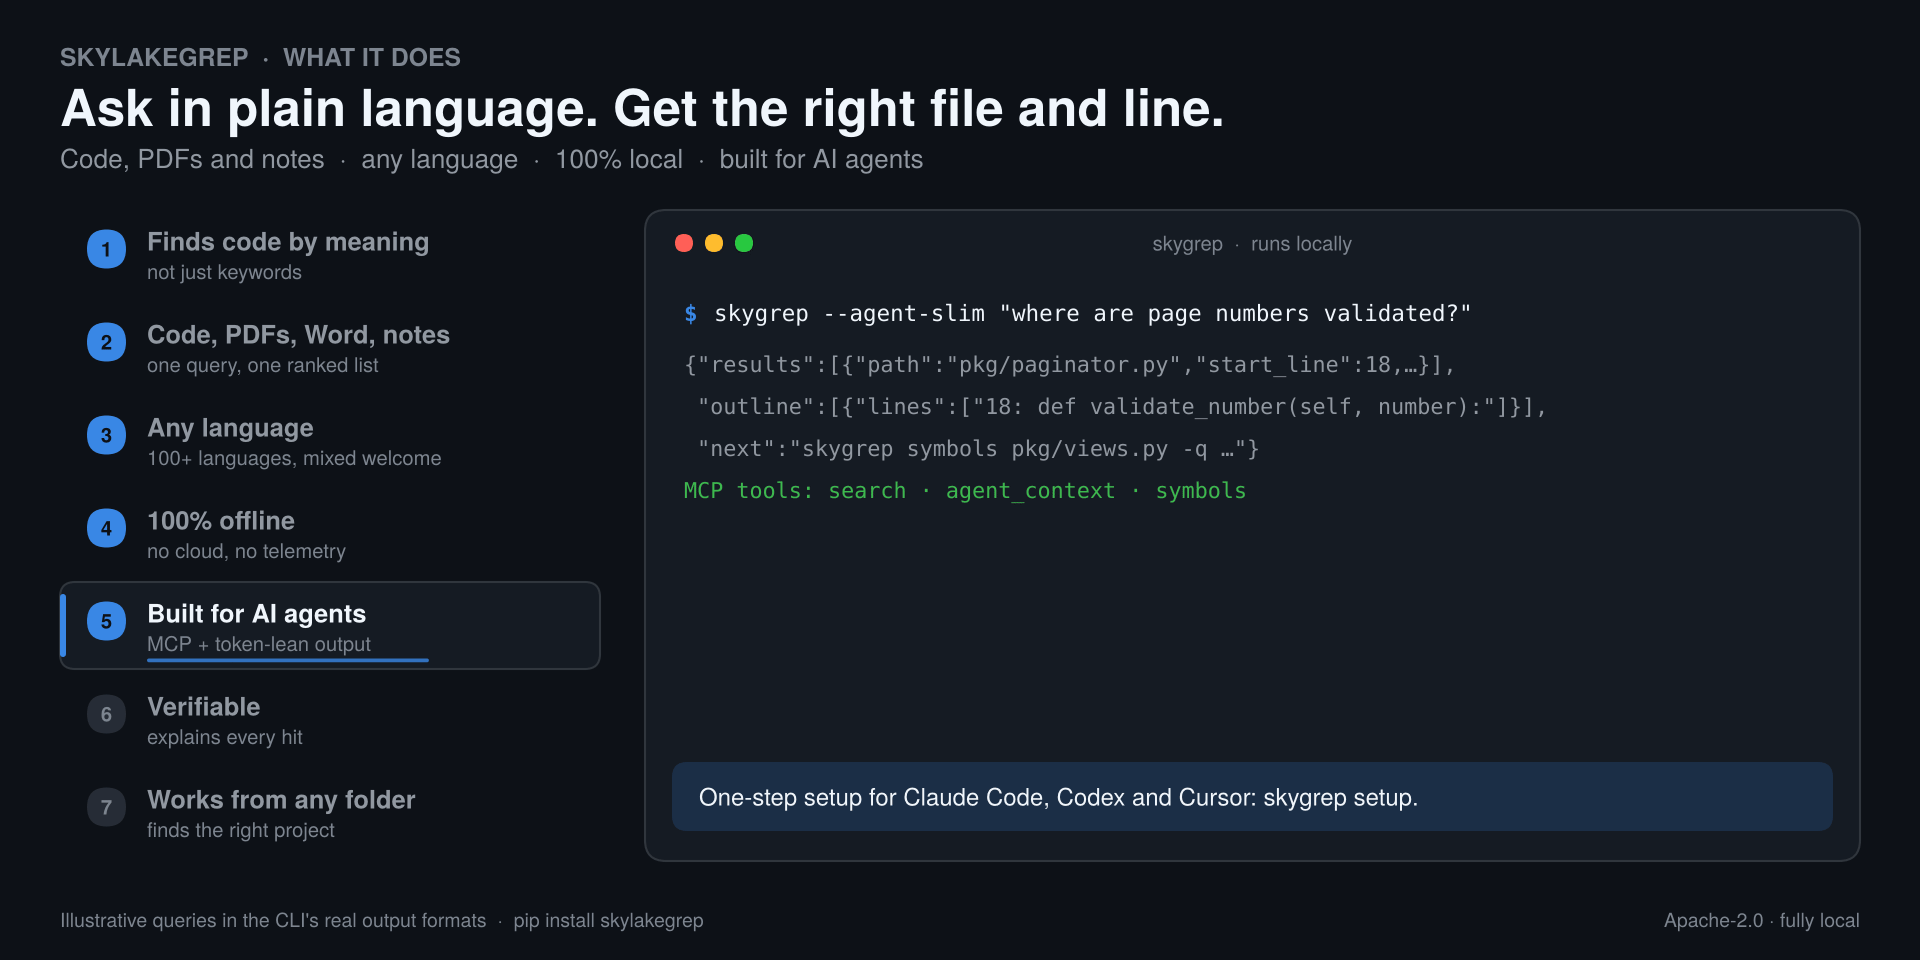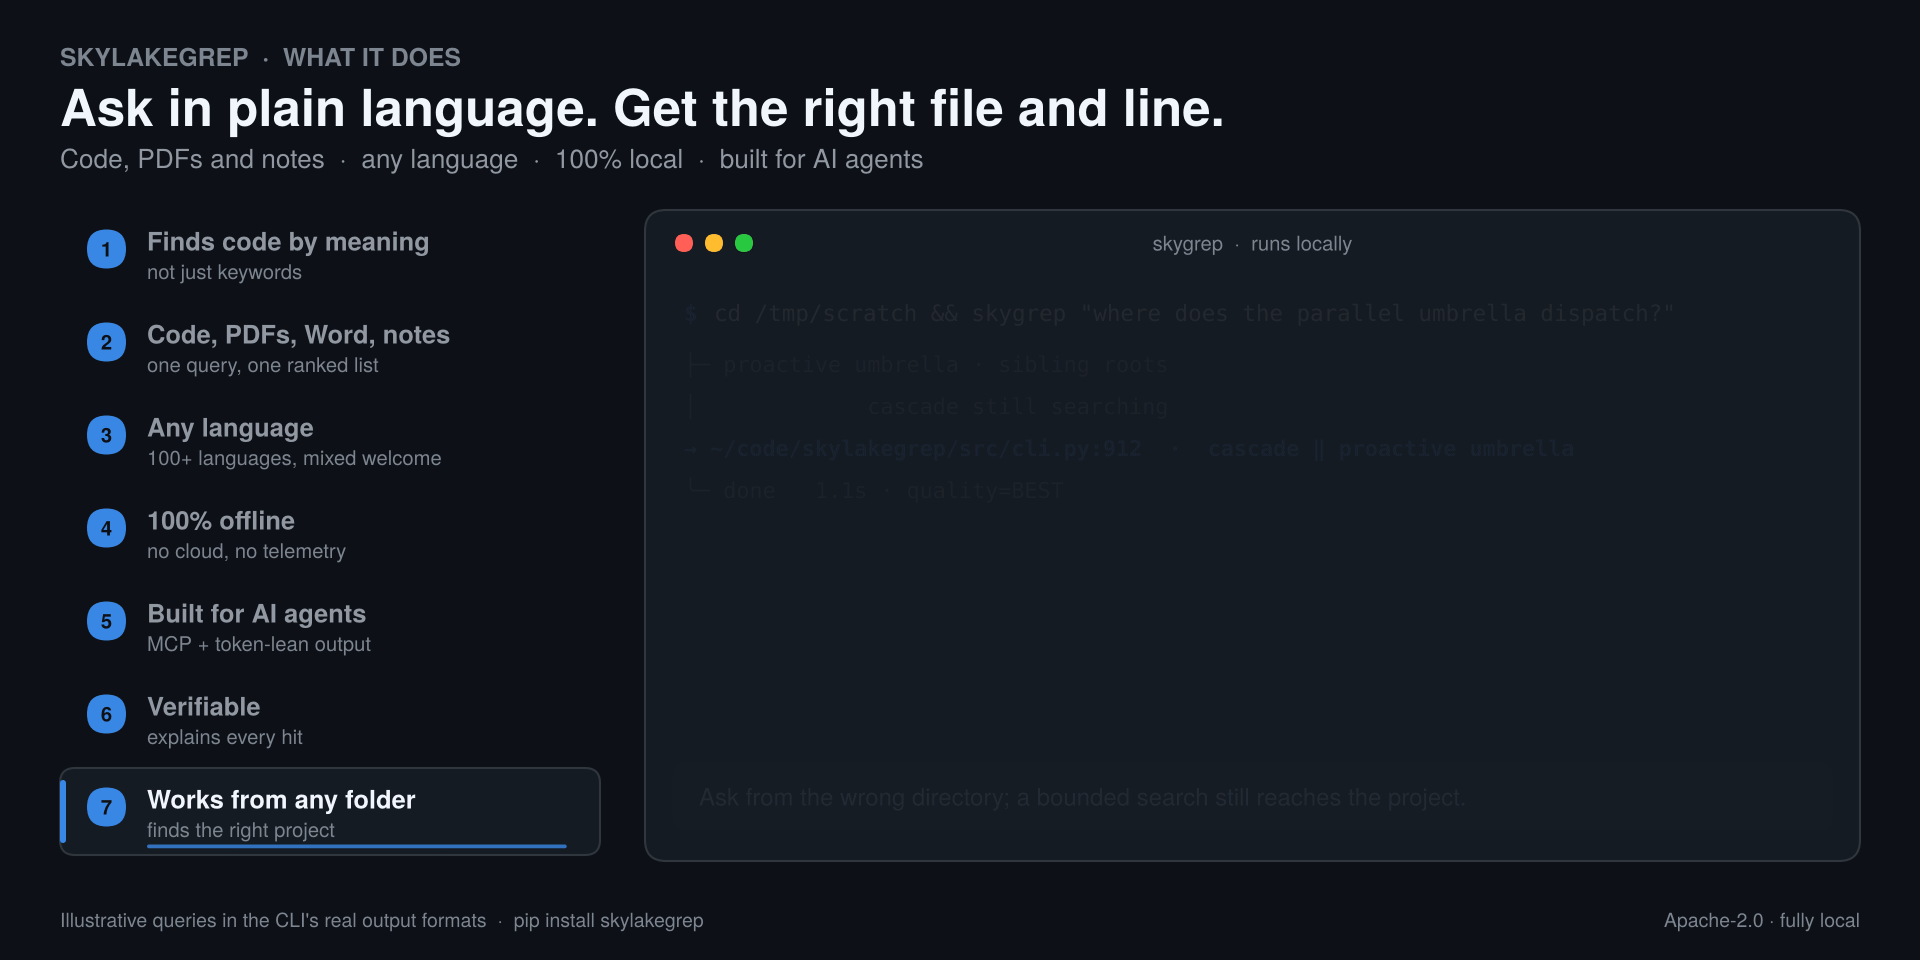
AGENT / JSON
Give another LLM structured context.
Agents should prefer --json over scraping terminal
output. Include a scope when the caller knows one; this avoids broad
home-folder exploration and gives the next LLM compact, relevant
evidence. Add --answer only when you want local synthesis
instead of source evidence.
$skygrep --json --content --detail standard --include "src/**" "where is token refresh implemented?"
$skygrep --answer --content --include "docs/**" "summarize the payment retry policy"
→ compact records with paths, scores, snippets, and route metadata
Lower token cost and less ambiguity for Claude Code, Codex, OpenCode, and other agents.
MCP
Native MCP MVP — Cursor verified.
skygrep mcp exposes two stdio tools — search and
agent_context — over the same retrieval pipelines as the CLI.
Verified in Cursor end-to-end (Connected + 2 tools + live tool call).
This is a retrieval component for existing agents, not a
do-everything coding agent. Ops (index / watch /
setup) stay on the CLI.
Why skylakegrep
vs. ripgrep · mgrep · autodev-codebase · Cody.
What makes skylakegrep distinct in the local-search landscape — sized
against four named alternatives, not generic categories.
comparison matrix · 2026
skylakegrep
v0.8.0
ripgreplexical baseline
Sourcegraph Codycloud commercial
Find by concept, not just token
✓
✗
✓
✓
✓
Privacy — no data egress
✓
✓
✗ cloud-backed
✓
✗ cloud index
Content — multimodal
code · md · PDF · docx
text only
code · text · PDF · img
code-first
code-first
Setup
pip install
brew install
npm + Mixedbread acct
npm + Ollama
account + sub
Cost
$ 0 / mo
$ 0 / mo
sub + usage-based
$ 0 / mo
$ 20 – 100+ / mo
Multilingual queries (NL → code id)
bge-m3 native
n/a
cloud embedder
embedder-dep.
supported
How it works
Router → two retrieval lanes race in parallel.
After the router classifies your intent, a σ-adaptive cosine cascade and a
parallel proactive umbrella search at the same time — not one after the
other. The first confident answer streams to your terminal; ranked
refinements arrive as later lanes finish. All against your local Ollama +
SQLite. Zero network.
vs Elasticsearch
Different niche, different design.
Elasticsearch is a multi-tenant, TB-scale, distributed search engine for
data centers. skylakegrep is a single-user, single-machine, zero-ops CLI
for a developer asking their own laptop a question.
capability matrix · skylakegrep 0.8.0 vs Elasticsearch 8.x
| skylakegrep 0.8.0 | Elasticsearch |
|---|
| Setup | pip install skylakegrep; cold-start lazy auto-trigger | JVM, cluster, mappings, ingest pipeline |
| Semantic retrieval | bge-m3 via local Ollama, out of the box | Manual embedder / pipeline / reindex |
| Privacy / offline | 100 % local by design | Index can be local; embeddings often external |
| Scale | single-machine, single-repo sweet spot | billions of docs, multi-shard, distributed |
| Multi-tenant / ACL | not designed for this | first-class |
Installation
Install the CLI and a local embedding model.
pip install skylakegrep
Prefer python3 -m pip install --user skylakegrep when your shell
has no bare python / pip. Then pull a local embedding
model via Ollama:
ollama pull bge-m3
ollama pull qwen2.5:3b
Full install, PATH fixes, clean reinstall, and agent setup live in the
CLI reference.
skygrep doctor
skygrep setup
Quickstart
Index a repository, then query it.
skygrep index /path/to/repo --reset
skygrep search "where is token refresh implemented?" -m 10
The first command walks the repository, chunks supported source files,
embeds each chunk via Ollama, and writes the result to
~/.skylakegrep/index.db. Subsequent runs re-index only
files whose modification time has changed and remove rows for files
that no longer exist.
For machine-readable output, add --json:
skygrep search "where is token refresh implemented?" -m 10 --json
Performance
60 pinned public tasks · source-evidence quality gates · paired efficiency statistics.
General Benchmark v2: 60 hand-validated tasks across six pinned public
commits (Cobra, Django, React, Spring Framework, Tokio, Vite). Efficiency
stats only for paired tasks that pass the same quality floor. The 2026-08-15
clean-source receipt passed those gates; tool calls and median eligible-task
latency did not improve. Numbers below are unchanged from that receipt —
full protocol on the linked pages.
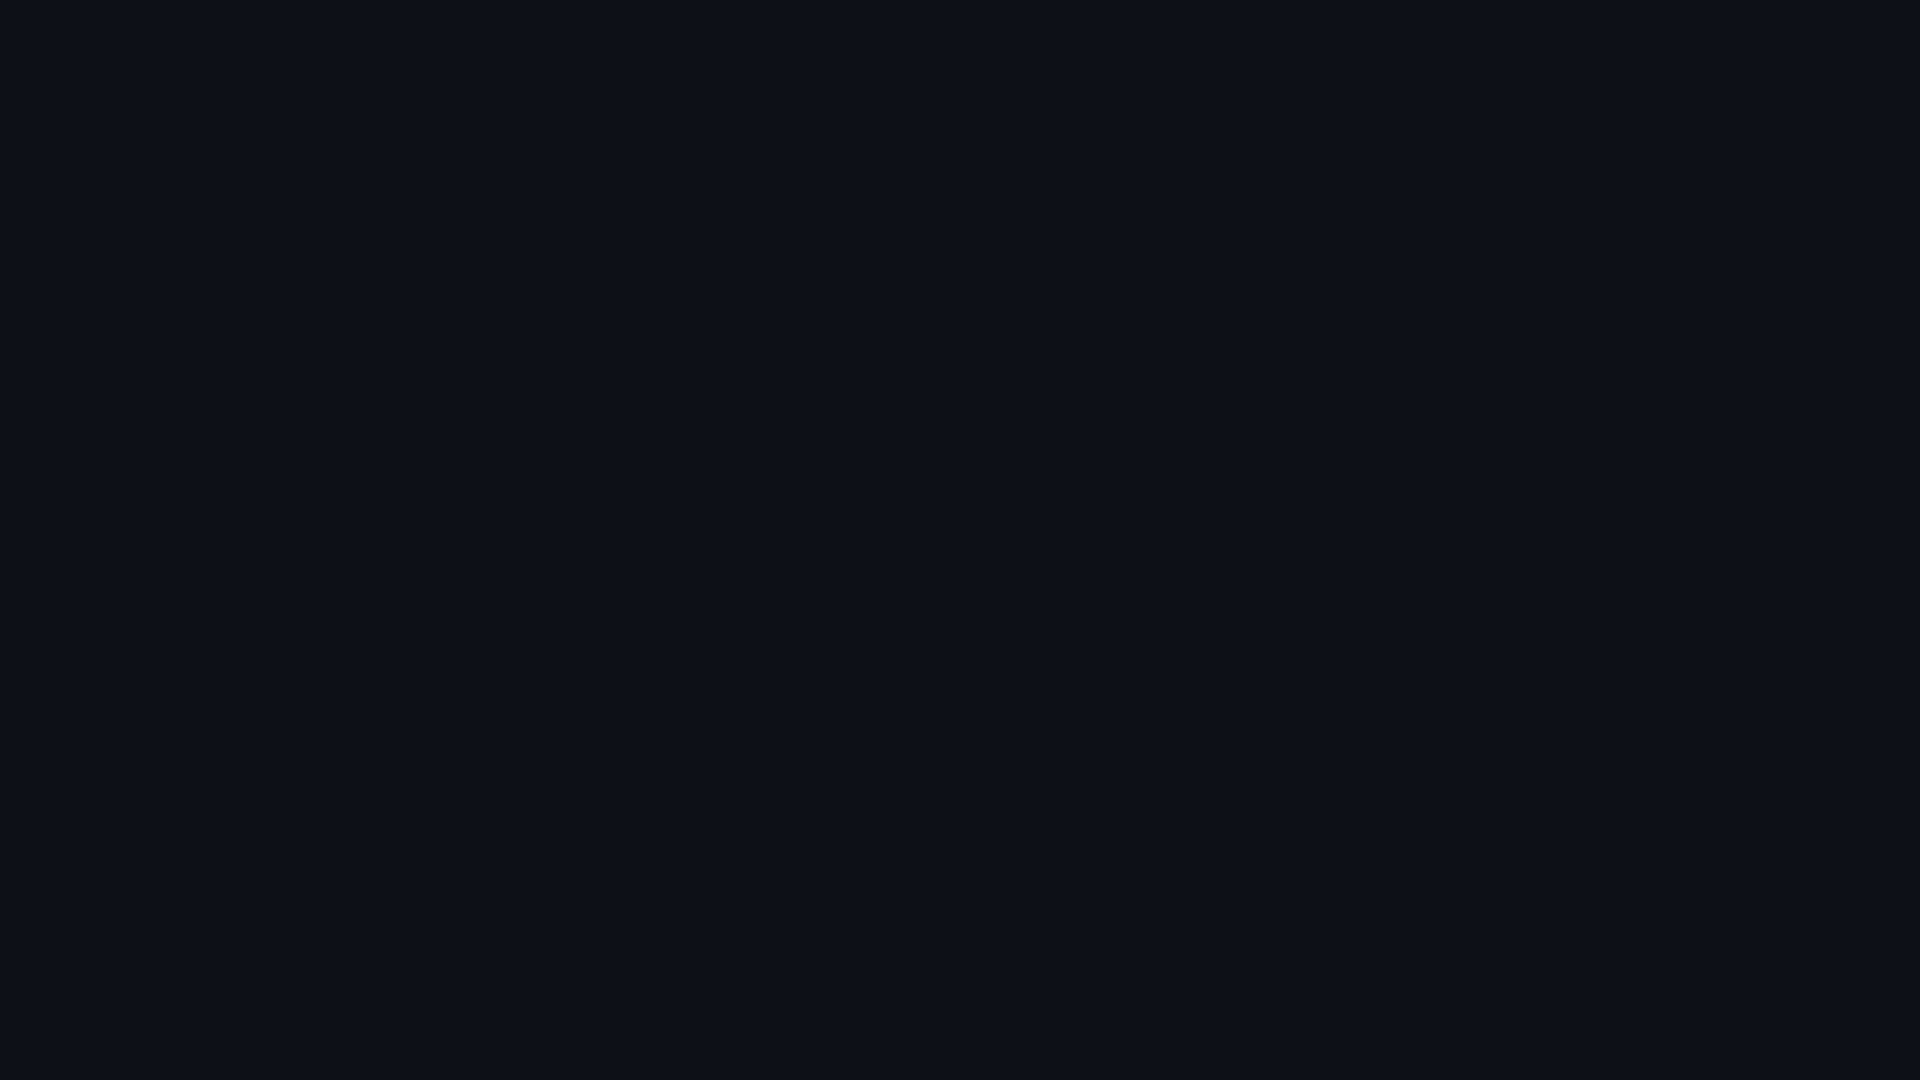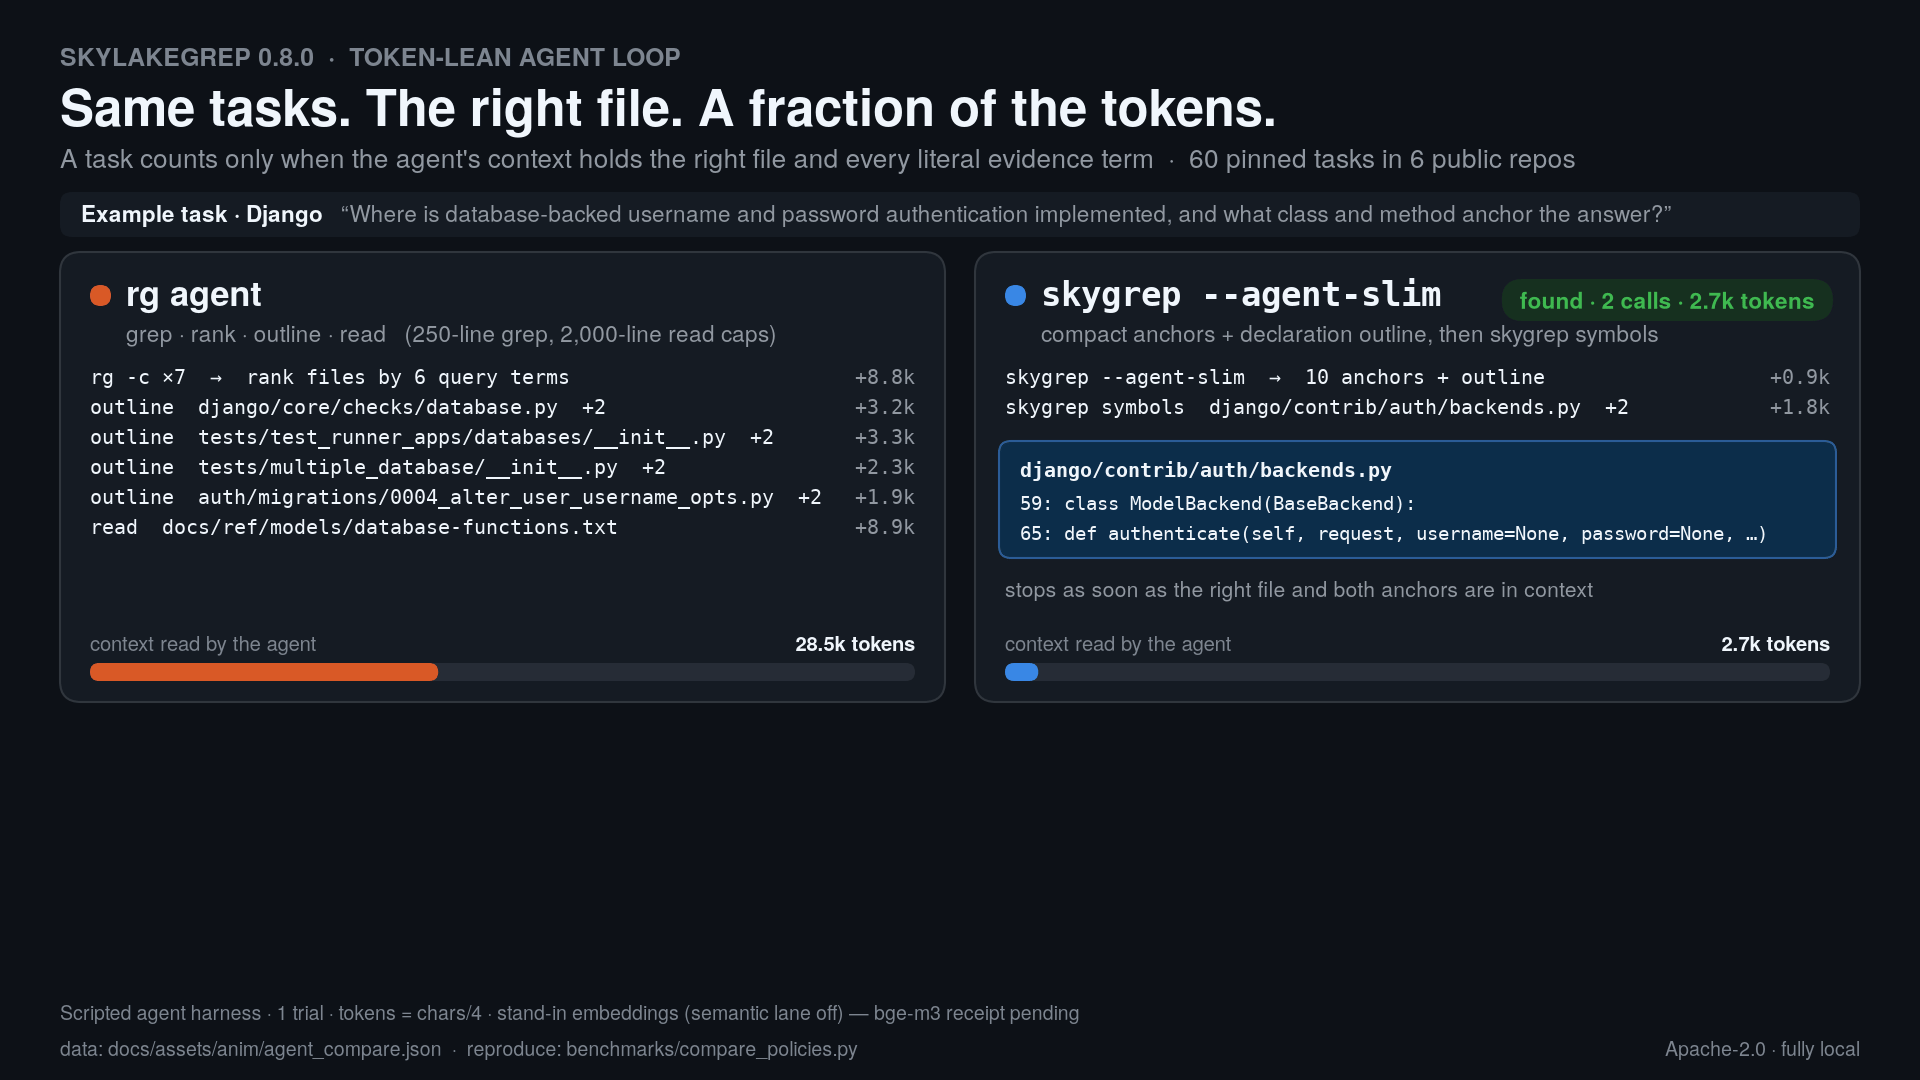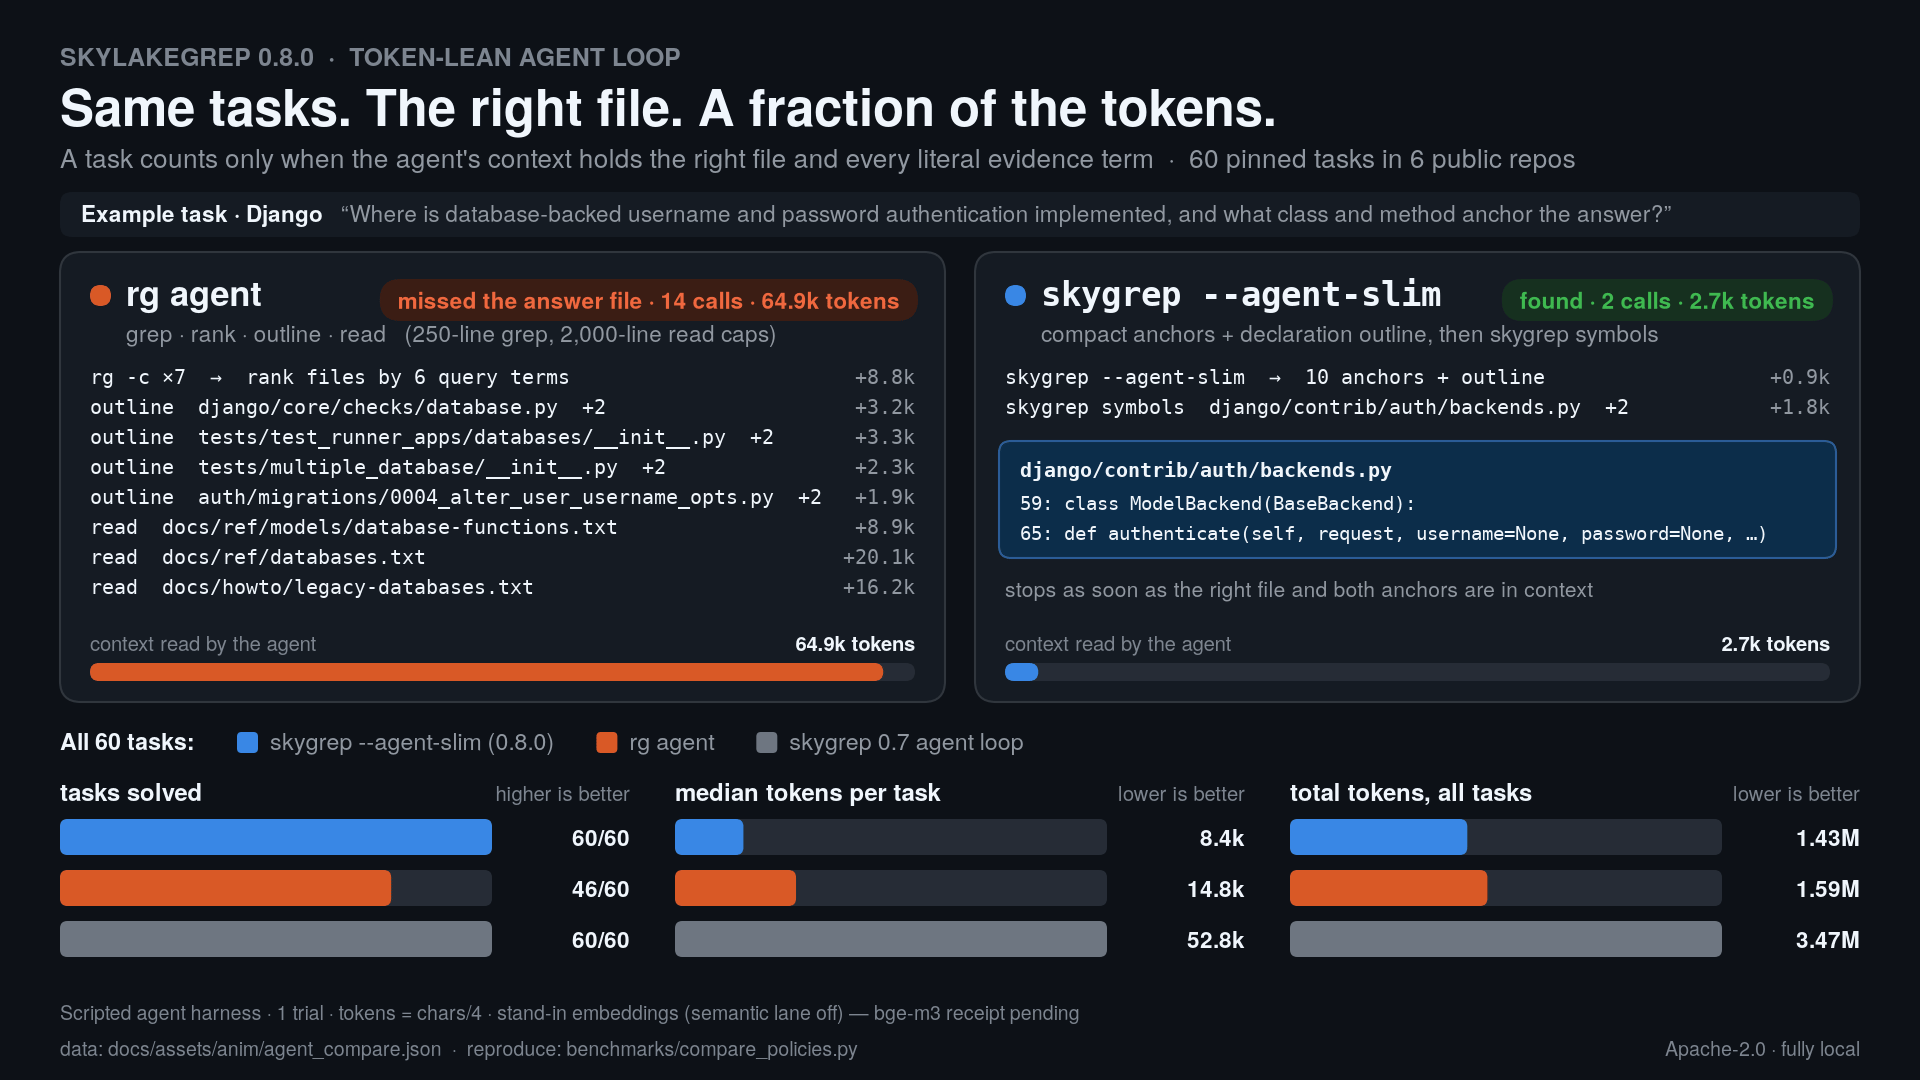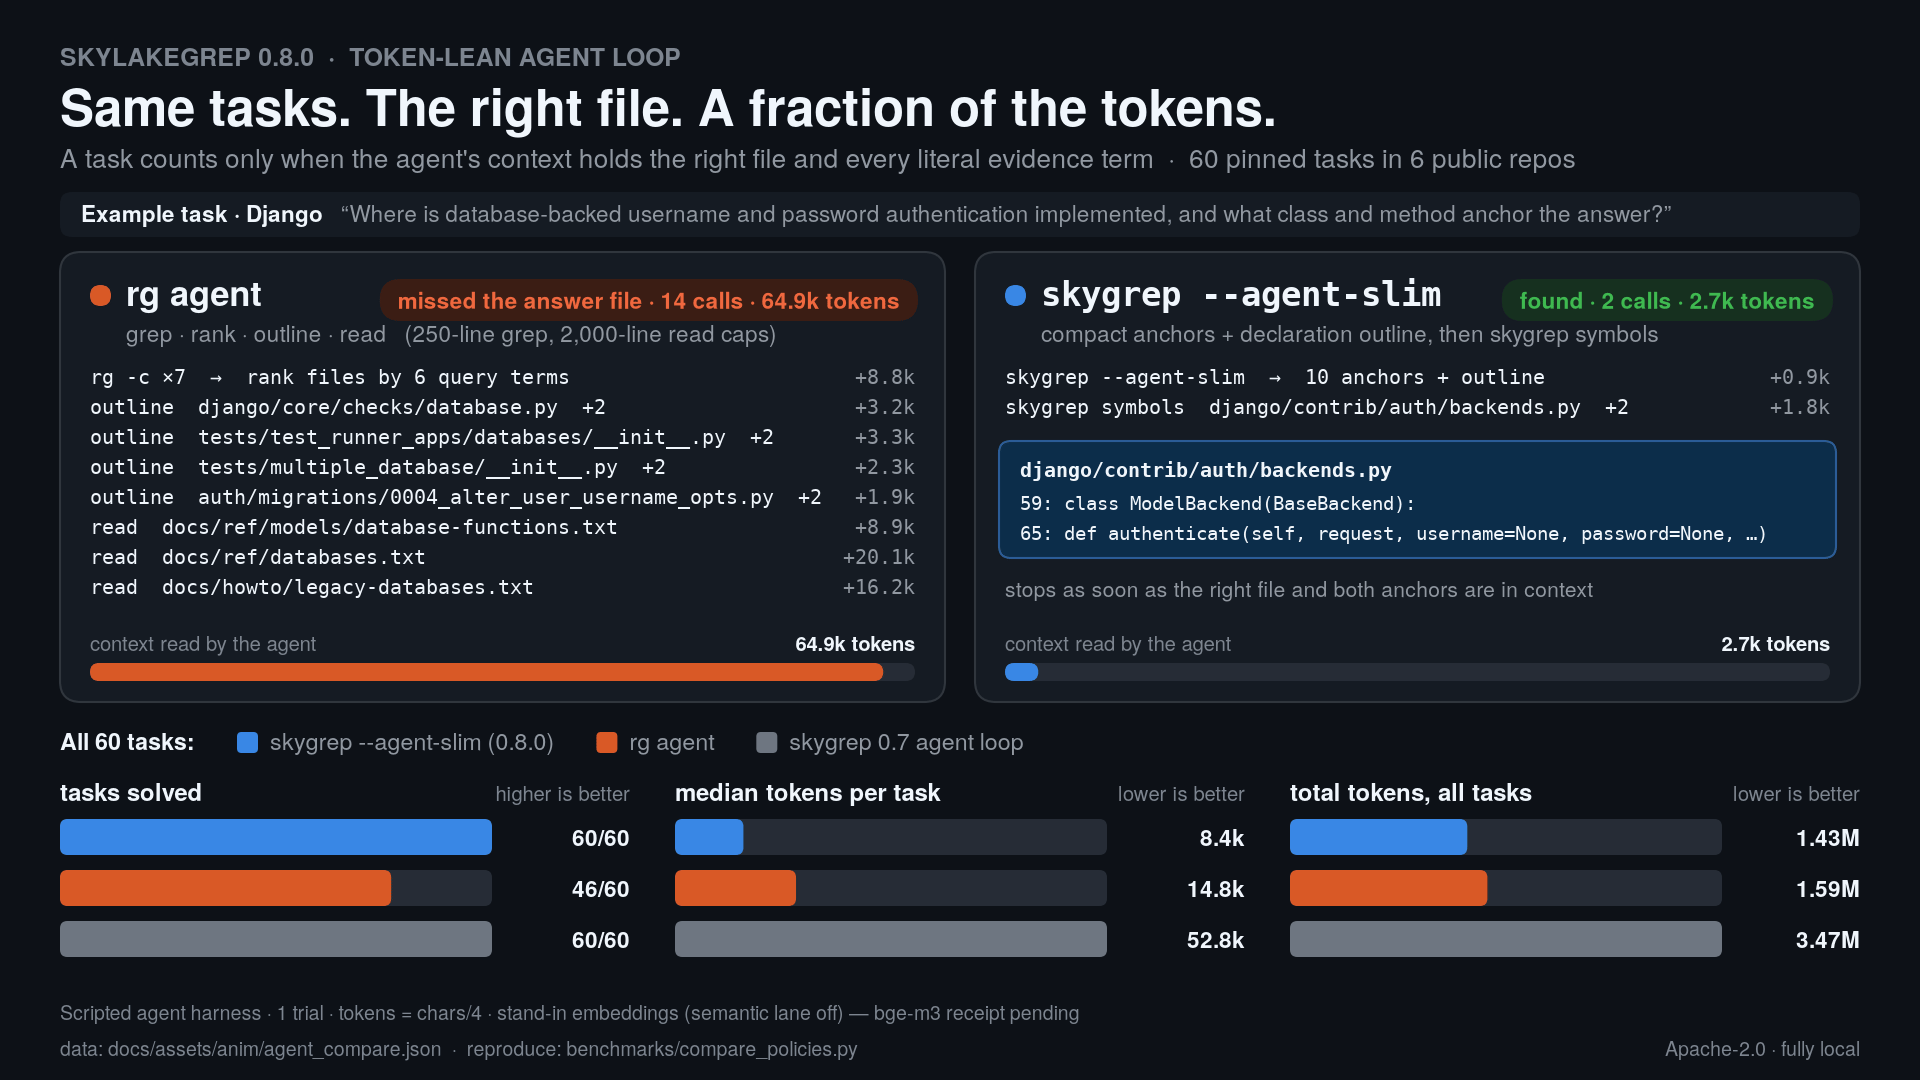
17.982×
median tool-context reduction
Only the 53 / 60 unique tasks where both policies passed quality ≥ 0.85. Baseline is an unbounded rg dump; see the token-lean policies in the general-performance page.
5.202×–94.127×
repository-aware 95% interval
Hierarchical bootstrap over repositories and unique tasks after combining three trials.
92.5% vs. 88.4%
retrieval-context quality
skygrep-first completed 180 / 180 observations; rg-only completed 159 / 180.
0.929×
paired median tool-call ratio
rg calls / skygrep calls: no tool-call reduction claim.
Honesty
What the data does and does NOT show.
-
It is a pinned retrieval benchmark, not a universal multiplier.
The result covers 60 hand-validated source-evidence tasks across six exact
public commits. Your repositories, queries, and hardware can differ.
-
Context reduction did not imply a typical-task speed win.
The eligible-task median
rg / skygrep harness-elapsed ratio was
0.561, so the median skygrep task was slower. Large outliers made the all-row
aggregate ratio 2.41 in skygrep's favor; neither is a universal latency claim.
-
Tool calls were not reduced.
The paired median
rg / skygrep call ratio was 0.929, and skygrep
used 2,014 calls versus 1,743 across all observations.
-
Quality is a retrieved-context proxy.
The gate verifies accepted paths, literal source evidence, noise control,
sufficiency, and stopping. It does not grade a downstream model's final answer
or include hidden reasoning and provider billing tokens.